2025 – present
VynixAI · Senior Solutions Architect, AI & Cloud Infrastructure
AI-driven, cloud-native, and edge platforms for real-time retail and enterprise workloads: RAG pipelines, scalable inference, and agent automation.
Open to consulting, collaboration, and roles
This headline started as a wordy prompt. Cutting the filler took it from about 22 tokens to 13. Same idea, applied to whole systems, is what I do.
I’m Iggy Mwangi, an AI systems architect in Dallas–Fort Worth with 25+ years of shipping software at Apple, Sam’s Club, AT&T, and Contran. I call my approach Compound Engineering: put the effort into the harness (context, checks, and fixed workflows) instead of waiting for a better model, so every system gets more reliable and the next one ships faster.
Below: free tools that run in your browser, field guides, and open-source code. No account needed.
Now VynixAI · Nubla AI Earlier Apple · Sam’s Club · Contran · AT&T Since 1998
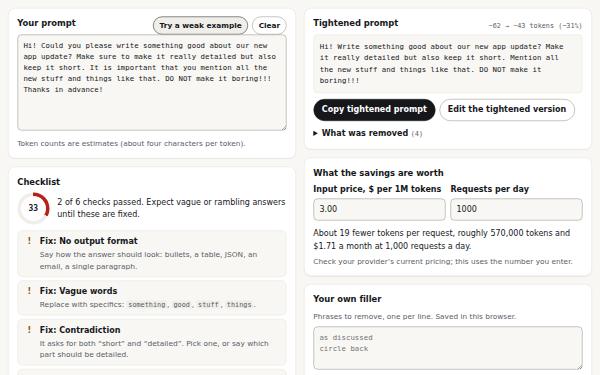
Paste a prompt, or pick an example. You’ll get a score, a list of what’s missing, a version with the filler words removed, and a rewrite with clear sections. It’s a small version of Prompt Matrix Evaluator, and everything happens in your browser.
Tightened
Each tool is a single page you can use right away. Every card says where your text goes, so you can choose the ones that fit your privacy needs.
Checks a prompt for a clear task, output format, length limit, audience, vague words, and contradictions, then cuts the filler and shows what that saves per month at your volume. A good first tool to try.
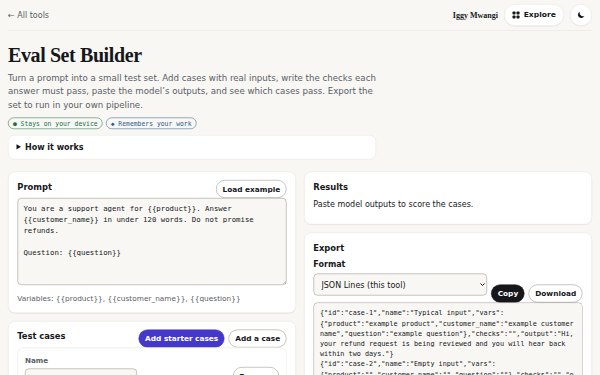
Turn a prompt into a test set. Add cases with real inputs, write the checks each answer must pass, paste the model’s outputs, and export the set to JSON Lines, promptfoo, or pytest.
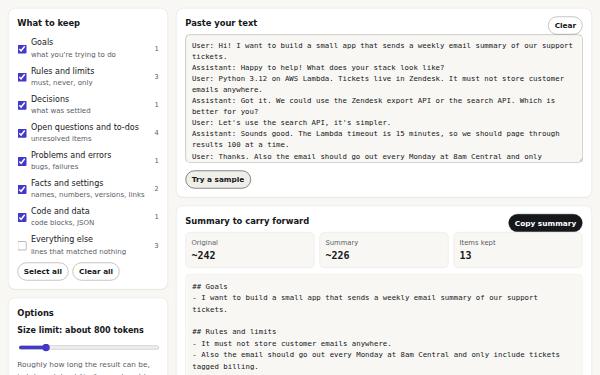
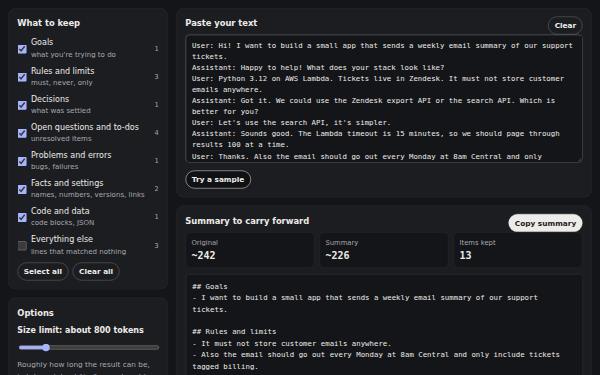
Paste a long chat or notes and get the goals, rules, decisions, open questions, and key facts. Untick or re-sort any item, then copy a ready-made handoff prompt for a fresh chat.
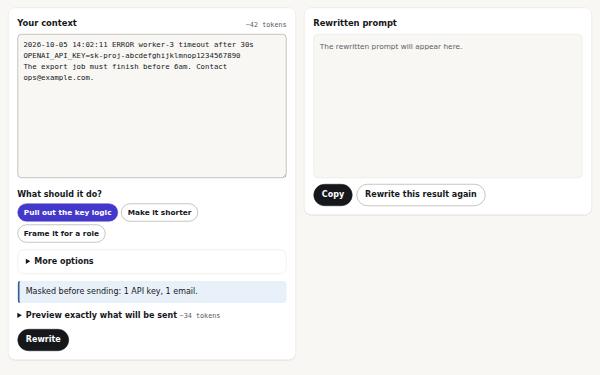
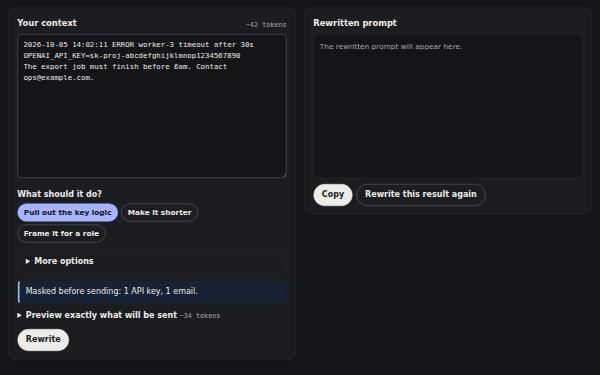
Rewrites messy logs, code, or notes into a tighter prompt using a hosted model. Secrets, emails, and phone numbers are masked before anything is sent, and you can preview exactly what goes out.
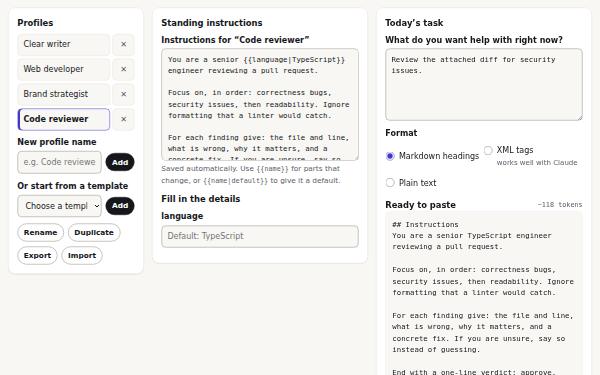
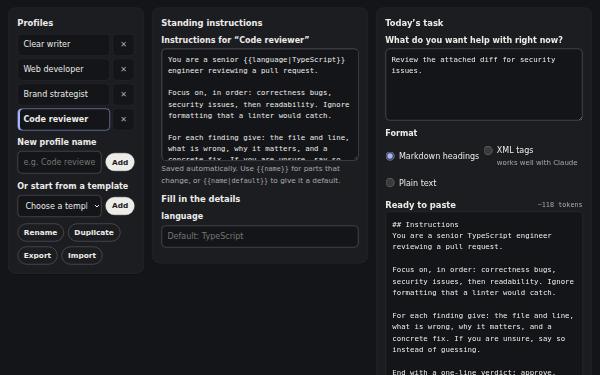
Reusable instruction profiles with fill-in variables and defaults, six starter templates, and Markdown, XML, or plain-text output for any AI chat or system prompt.
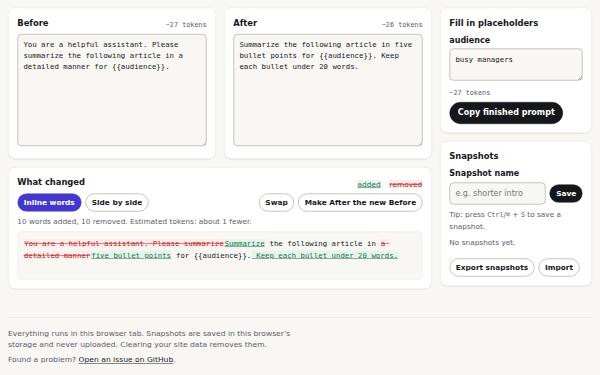
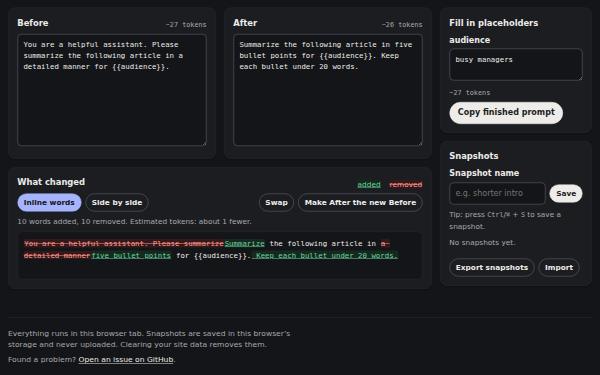
Compare two prompt versions inline or side by side, fill in placeholders, and keep snapshots you can export, import, and roll back to.
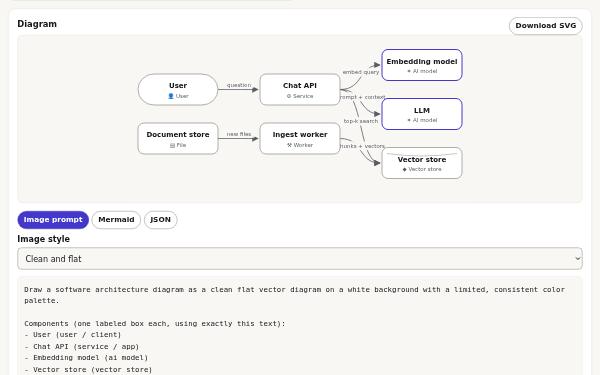
Describe components and connections to get a live architecture diagram. Download it as SVG, paste Mermaid into your docs, or copy a prompt for an image model.
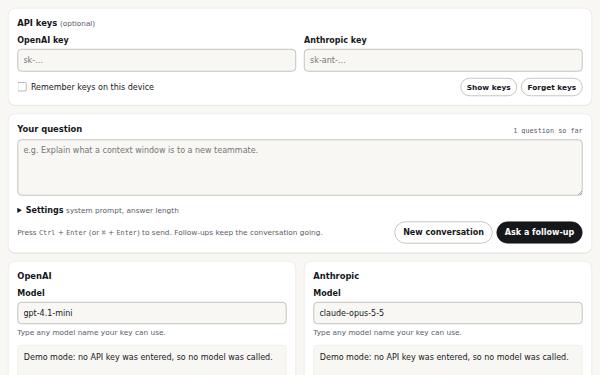
Ask OpenAI and Anthropic models the same question side by side, with follow-ups, a shared system prompt, response times, token counts, and a Markdown export.
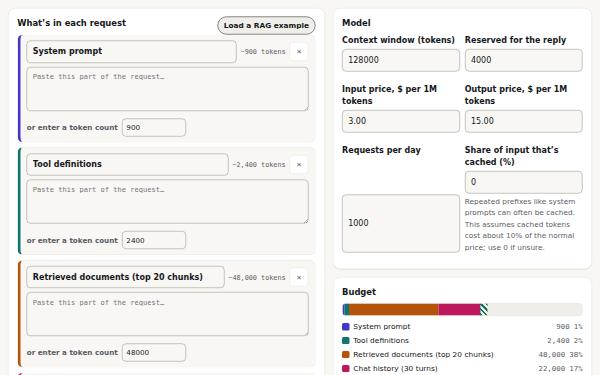
Plan how much text fits in one request. Budget each part of the prompt, check there’s room for the reply, see the monthly cost, and find what to cut first.
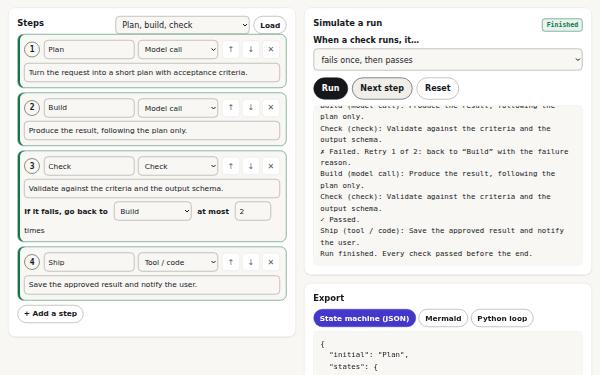
Sketch an AI agent as a fixed list of steps, each with a check and a limit on retries. Simulate failures, then export a spec, a diagram, or starter Python code.
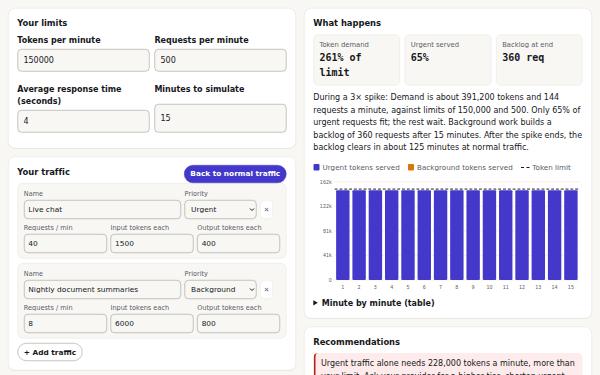
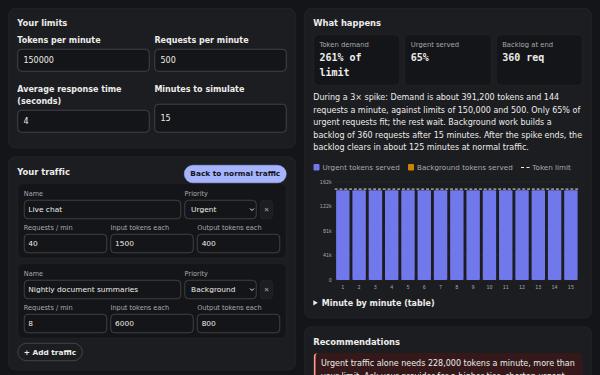
Enter your API rate limits and traffic to see whether you’ll hit them. Also see how urgent requests stay fast when things are busy, and how long a backlog takes to clear.
Field guides I keep current on GitHub, essays from this site, and seventeen subject sites. Subscribe to new essays (Atom feed).
Open-source code on GitHub. Free to read, use, and adapt under each repo’s license.
Open to consulting, collaboration, and roles.
Harness over model. Most AI failures I’m called in for aren’t model problems; they’re missing context, missing checks, and agents left to improvise. I fix the harness around the model, and each fix becomes a reusable part, so the second system costs a fraction of the first.
2025 – present
AI-driven, cloud-native, and edge platforms for real-time retail and enterprise workloads: RAG pipelines, scalable inference, and agent automation.
2024 – present
ML systems and cloud architectures across AWS, Azure, and GCP, focused on LLM integration, retrieval, and dependable ML pipelines.
2022 – 2023
Cloud modernization across AWS and Apple’s internal platforms: replaced lift-and-shift workloads with serverless and container designs, moved pipelines to event-driven architectures, and led FinOps work.
2017 – 2021
Cloud ML for forecasting, computer vision, and real-time analytics, plus retail line-of-business apps on Azure, iOS, and Android at retail scale.
2011 – 2017
Unified fragmented mobile, web, and backend systems across iOS, Android, AWS, and GCP for long-running operational workflows.
Earlier, 1998 – 2011: AT&T, Verizon, Cingular, EDS, ADP, IBM Innovation Center, BP-Amoco, Williams Communications, and others. B.Sc. Computer Science, University of Minnesota.
Baselines and methods aren’t published here. The work falls under confidentiality agreements with my employers. I’m glad to discuss the details under NDA.